Plugin Development Overview
A Firecube plugin is a Python package that teaches Firecube how to turn source data into a product. Most plugins contain the product-specific reading and data shaping, while a Firecube template provides source discovery, batching, standard storage writes, run tracking, and recovery around that code.
This guide assumes Firecube is installed and its environment is activated
with source .venv/bin/activate. See
Installation if you still need to set up
an environment.
Want a complete worked example instead? The Quickstart runs an installed NetCDF-to-Zarr plugin. Showcase has notebooks for incremental ingestion, real-world datasets, and parallel benchmarks.
How Template Plugins Work
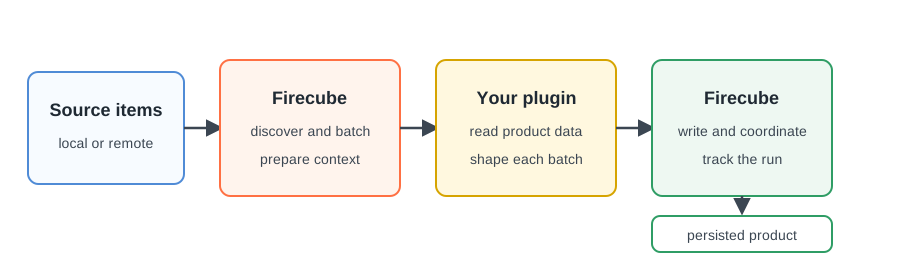
Most plugin authors use one of the three template classes. A template keeps the plugin focused on product data while Firecube uses its standard writer. A custom pipeline is available when none of those contracts represents the product.
Choose What Your Plugin Produces
| Product contract | Start with | Your plugin supplies |
|---|---|---|
| Complete, ordered multidimensional datasets | Append Datasets To Zarr with GenericZarrIngestor (concept) |
One xarray.Dataset for each group and batch; Firecube serializes appends to a group |
| Tables or data frames | Write Tables To Parquet with GenericParquetIngestor (concept) |
One table or data frame for each group and batch |
| Zarr data with known indexed positions, especially when several workers must write one group | Declare The Schema And Index with DirectZarrIngestor (concept) |
The array schema and write locations; for parallel workers, a fixed extent and deterministic index model |
| The same, but the timestamps are only known after reading the files | Discover The Time Axis with DirectZarrIngestor and TimeAxis.discovered |
The array schema and a timestamp per item; Firecube builds the axis before writing |
| A product no template represents | Custom Pipeline Plugins — the advanced, manual contract; use it when the templates above don't fit | Processing, writing, results, and coordination |
Start with Append Datasets To Zarr unless your product is tabular or needs parallel workers on one group. The source file format does not determine the class. Choose the contract that matches the data your plugin can supply.
For Zarr, the important difference is how a write position is chosen.
GenericZarrIngestor finds the end of the group and appends the next complete
dataset, so mutations to that group pass through one serialized append path.
DirectZarrIngestor places writes at indexes supplied by the plugin. Its
optional parallel contract fixes the global extent first, then lets separate
ingest processes own disjoint, chunk-aligned ranges of the same group.
Choose DirectZarrIngestor only when exact placement or same-group slot
parallelism justifies the additional schema and indexing work. The class also
supports serial ingestion; selecting it does not enable parallel writes by
itself. Compare the Zarr write models
before implementing the plugin.
From An Idea To A First Run
- Choose the product contract. Use the table above to identify the public class that matches the data the plugin will supply.
- Create the plugin. The interactive command creates a Python package for the selected class.
- Install the plugin. Install it in development mode so Firecube can discover it while you edit the code.
- Discover the source data. See which files Firecube finds and what your plugin receives. If they are archives, read Discover Zipped Data; if the date is in the file name or a time step spans several files, see Parse Filename Fields and Read Paired Source Files.
- Write the output. Append Datasets To Zarr or Write Tables To Parquet; run on a few files and check the result.
- Choose the Zarr layout. For a Zarr cube, decide chunking, and if needed sharding and compression, before the first real run. A written cube keeps its layout.
- Add configuration options. Turn hard-coded
values into
--optionsettings. - Package and register the plugin. Declare the package entry point so Firecube can discover the plugin from installed metadata.
Several workers writing one Zarr group at the same time is a separate contract: Write Zarr Regions In Parallel.
Next Steps
- Create a Plugin — create a package with the interactive command
- Zarr Write Models — compare sequential appends, direct writes, and optional parallel writes
- Quickstart — run an installed plugin from source files to a verified Zarr product
- Firecube 101: NetCDF To Zarr — create a reader and verify its stored values
- API Reference — look up the public types used by template plugins